Unmasking True Clinical Competence: The Importance of Adaptive and Open-Ended Evaluation for Large Language Models in Cardiology
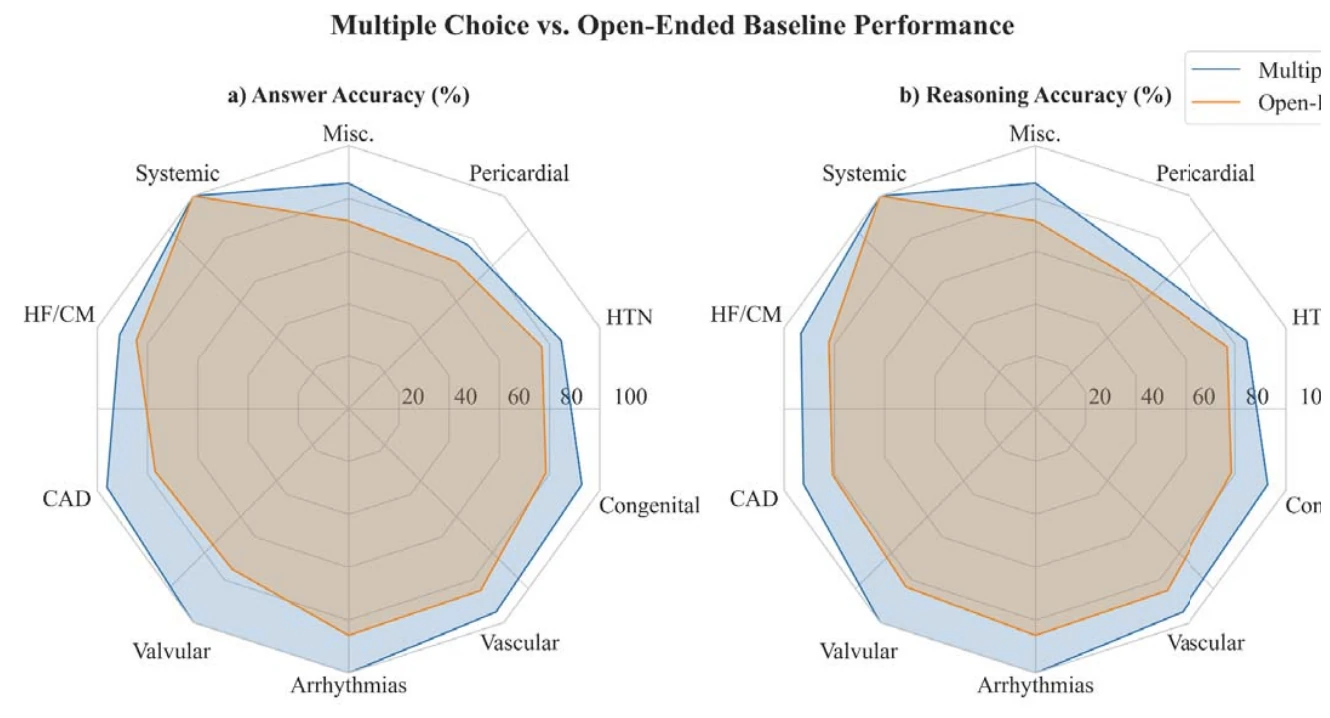
Multiple-choice scores make LLMs look better at cardiology than they are. Open-ended and clinically modified questions expose the gap.
Abstract
Background: Large language models (LLMs) achieve impressive accuracy on multiple-choice (MC) medical examinations, but this performance alone may not accurately reflect their clinical reasoning abilities. MC evaluations of LLMs risk inflating apparent competence by rewarding recall rather than genuine clinical adaptability, particularly in specialized medical domains such as cardiology.
Methods: We assessed GPT o1-preview using 185 board-style cardiology questions from the American College of Cardiology Self-Assessment Program (ACCSAP) in MC and open-ended formats. A subset of 66 questions underwent modifications of critical clinical parameters (e.g., ascending aorta diameter, ejection fraction) to evaluate model adaptability to context changes. The model's answer and reasoning correctness were graded by cardiology experts.
Results: GPT o1-preview demonstrated high baseline accuracy on MC questions (93.0% answers, 92.4% reasoning). Performance significantly decreased with open-ended questions (80.0% answers, 80.5% reasoning; p<0.001). For modified MC questions, accuracy decreased significantly (answers: 93.9% to 66.7%; reasoning: 93.9% to 71.2%; both p<0.001), as did answer-reasoning concordance (93.9% to 66.7%, p<0.001).
Conclusions: Using existing MC question formats substantially overestimates the performance and clinical reasoning capabilities of GPT o1-preview. Incorporating open-ended, clinically adaptive questions and evaluating answer-reasoning concordance are essential for accurately assessing the real-world clinical decision-making competencies of LLMs in cardiology.
Cite
@article{chao2025unmasking,
  title = {Unmasking True Clinical Competence: The Importance of Adaptive and Open-Ended Evaluation for Large Language Models in Cardiology},
  author = {Chieh-Ju Chao and Abhinav Kumar and Aakash Mishra and Yu-Chiang Wang and Chieh-Mei Tsai and Nima Baba Ali and Somanshu Sharma and Juan M. Farina and Reza Arsanjani and Yucheng Jiang and Monica Lam},
  year = {2025},
  journal = {medRxiv},
  doi = {10.1101/2025.05.17.25327814}
}